Uso delle massimazioni e dei collegamenti esplicativi di una banca dati giuridica per allenarne una concorrente: il caso Westlaw

Interessante provvedimento dell’appello del 3° circuito, Thomson Reuters contro Ross Intelligence,  29.09.2026, nr 25-2153. Il caso tratta dell’utilizzo non autorizzato delle headnotes della banca dati giuridica Westlaw come allenamento (training) dell’applicazione AI creata da Ross, sempre nel settore dell’ausilio alle ricerce giuridiche.

Questa la condotta di Ross censurata:

<<ROSS then created an AI legal search engine that would respond to plain-language legal questions with relevant pas-sages of text from judicial opinions. ROSS had access to a bank of approximately ten million uncopyrighted judicial opin-ions from which it could respond with an excerpt relevant to a user’s query. ROSS’s AI was not a generative AI, meaning it would not create any new expression; it would only return text passages from preexisting judicial opinions.

For ROSS’s AI legal search engine to work, the AI program had to learn what made a judicial opinion responsive to a user’s legal question. To train its AI program to do so, ROSS enlisted a company called LegalEase Solutions (“LegalEase”) to create AI training memoranda. LegalEase wrote approximately 25,000 legal memos, each of which presented a legal question and four to six judicial opinion passages in response. Memo-drafters for LegalEase, and its subcontractor Morae Global, used thousands of Westlaw headnotes to create the memos’ legal questions, as the headnotes provided “an easy way [to] fram[e] questions.” App. 8545. The memos’ responses to the legal questions needed to include at least one great, good, top-ical, and irrelevant judicial opinion passage, labeled as such. A great passage was completely responsive; a good passage was mostly responsive; a topical passage was somewhat re-sponsive; and an irrelevant passage was not responsive. The “[g]reat” passages were “[m]ost frequently” the judicial opin-ion passages that Westlaw linked to the headnote that ROSS used as the memo’s legal question.2 App. 4837–39. These memos were then converted into a machine-readable format and used to train the ROSS AI program to identify patterns re-garding which judicial opinion passages respond well to legal questions.

ROSS did not hide its intention that this for-profit AI plat-form compete with Westlaw. ROSS ran ads directly compar-ing its platform to Westlaw at prices “in line with” Westlaw. App. 4519. ROSS executives hoped ROSS would serve as a substitute for Westlaw, and some law firms switched from us-ing Westlaw to ROSS.>>

Potrebbe essere interessante anche il fatto  che le headnotes siano ritenute proteggibili: dico “potrebbe”, perché bisognerebbe prima esaminarle in dettaglio, ma sono quasi sconosciute in Italia (tranne che nei maggiori studi legali in Roma e Milano , forse)

Anche negli Stati Uniti la protezione viene concessa con una soglia minima di originalità, si desume dalla opinion.

Più interessante è il fair use, che viene negato a Ross, e in particolare il quarto fattore, cioè quello del market effect, originario e derivato (a valle).

E il market effect è giudicato a favore di Thomson Reuters: spt. interessa il mercato a valle del licensing dell’uso delle headnotes.

<<We begin with the original market. The parties dispute which is the relevant original market. ROSS argues that the relevant original market is the market for headnotes as a standalone product, which ROSS claims does not exist. Even assuming this is the relevant market, ROSS’s argument ignores the effect of ROSS’s use on the value of Thomson Reuters’s headnotes. Our Court rejected a similar argument in Video Pipeline, Inc. v. Buena Vista Home Entertainment, Inc., 342 F.3d 191, 202 (3d Cir. 2003), abrogated in part on other grounds by TD Bank N.A., 928 F.3d at 278. There, a website that published trailers and clips of Disney movies argued that no market existed for movie trailers because no one “ever paid or will ever pay any money merely to see trailers.” Id. at 202. We rejected that argument, stating that “[t]he [fair use] statute directs us to consider the effect of the use upon the . . value  of the copyrighted work, not only the effect upon the market, however narrowly that term is defined.” Id. (emphasis in orig-inal) (citation modified). Video Pipeline’s publishing of the trailers damaged the trailers’ value in drawing users to Dis-ney’s website, where Disney could induce purchases or cross-market other products; it made no difference that no standalone trailer market existed. Id. The same is true here. While there may be no standalone market for headnotes, Thomson Reuters touts the headnotes as a feature to attract users to buy a Westlaw subscription. By copying the headnotes and using them to build its own competing legal-research platform, ROSS appropriated the headnotes’ value for finding and ana-lyzing judicial opinions and diminished their value as a draw for users to Thomson Reuters’s legal-research platform. So, Video Pipeline supports the conclusion that ROSS’s copying harmed the value of Thomson Reuters’s headnotes.

Thomson Reuters argues that the legal-research platform market is the relevant original market. ROSS offers no con-vincing reason to ignore this market, so we consider it. The undisputed evidence here reveals that ROSS copied the head-notes to create a competing legal-research platform in the same market as Westlaw. “[U]nrestricted and widespread” copying of Thomson Reuters’s headnotes to develop substitute legal-research tools, like ROSS did, would harm Westlaw’s position in that original market. Andy Warhol, 598 U.S. at 524 n.3 (quoting Campbell, 510 U.S. at 590). ROSS offers no evidence to rebut the alleged harm in this market.

We turn now to potential derivative markets for Thomson Reuters’s headnotes. The parties dispute the relevant potential derivative market. ROSS argues it did not harm any potential derivative market because no derivative market for headnotes exists. Thomson Reuters argues that ROSS harmed its position in the potential derivative market for licensing headnotes as AI training data. “The market for potential derivative uses in-cludes only those that creators of original works would in gen-eral develop or license others to develop.” Campbell, 510 U.S. at 592. But a potential derivative market is not illusory just because an author “has evidenced little if any interest in ex-ploiting this market for derivative works.” Castle Rock Ent., Inc. v. Carol Publ’g Grp., Inc., 150 F.3d 132, 145–46 (2d Cir. 1998).

Here, the evidence shows that the market for licensing headnotes as text to train AI is rapidly developing. Addition-ally, Thomson Reuters presented evidence that it is using its headnotes as training data for its own AI search products. ROSS offers no evidence to disprove this.    That Thomson Reu-ters did not license its headnotes to others does not disprove that a market exists to do so. Additionally, ROSS’s copying harmed Thomson Reuters in this market. By copying the head-notes for use as training data without Thomson Reuters’s au-thorization, ROSS usurped Thomson Reuters’s opportunity to enter that derivative market and license its headnotes for that purpose. The market harm caused by ROSS’s use weighs against fair use.

In particolare Ross dice che il market di Thomson è il market delle headnotes, come standalone product. E secondo Ross non esiste. Invece Thomson Reuters dice che il relevant original market è il legal research platform e qui la corte accoglie.
Protezione del personaggio di fantasia col diritto d’autore: rigettata in via definitiva la domanda contraffattoria di Unidis Jolly Film c. Paramount per «The Man with No Name» e di Clint Eastwood

Cass., sez 1, 1 maggio 2026 n. 12.257, rel. Falabella, rigetta il ricorso di Unidis v. Paramount per la pretesa violazione del suo personaggio

Per la decisione di appello v. mio post 12.09.2022.

La Sc in sostanza conferma che non si tratta di scindibilità del personaggio dall’attore, requisito non previsto dalla legge; si tratta piuttosto di assenza di originalità nel personaggio, soverchiata dalla notorietà dell’attore, unico elemento ripreso.

<<Premesso che la tutelabilità del personaggio, che è indipendente
dalla protezione accordata all’opera (quale quella letteraria, teatrale,
cinematografica, televisiva, radiofonica, musicale, ma anche
fumettistica o del videogioco) in cui il personaggio stesso si colloca
(Cass. 30 dicembre 2022, n. 38165, in motivazione), discende dalla
caratterizzazione che rende il personaggio stesso riconoscibile quale
creazione tipica (Cass. 20 febbraio 1978, n. 810), il giudizio espresso
dalla Corte di appello, circa l’assenza di una riconoscibile connotazione
creativa nel personaggio, vale a dire di una precisa distinguibilità dello
stesso dagli archetipi di genere, unito alla constatazione della precisa
corrispondenza tra «L’uomo senza nome» e Clint Eastwood, interprete
cui il film «Rango» rimandava, doveva evidentemente condurre, come
naturale conseguenza logica, ad affermare che il personaggio non era
scindibile dall’attore e finiva, quindi, per immedesimarsi con lui.
L’identificazione di «The Man with No Name» con Eastwood muove, in
conclusione, dall’accertamento circa l’insufficiente caratterizzazione del
personaggio rispetto a stereotipi tradizionali — accertamento che,
investendo un profilo di fatto, sfugge, ovviamente, al sindacato di
legittimità —, nella univoca identificazione dell’uno nell’altro, oltre che
nel richiamo del lungometraggio a connotazioni proprie di Clint
Eastwood.
La pronuncia impugnata si sottrae, così, a censura. Infatti, se è
vero che il personaggio cinematografico in quanto tale è tutelabile
giuridicamente, il suo plagio è da escludere allorquando ricorra una
insufficiente caratterizzazione di esso rispetto a modelli di genere e,
risultando il personaggio medesimo rappresentato da un unico attore,
si abbia ragione di credere, anche a causa dei rinvii della pellicola a
elementi caratterizzanti la figura di quell’interprete — e non a quella
della creazione di fantasia — che il reale oggetto dell’attività di
sfruttamento denunciata concerna proprio l’artista>>.

Lo sviluppo dell’ A.I. generativa su materiali protetti da diritto d’autore ne comporta la violazione? Probabilmene si, secondo la 3° parte dello studio dell’ US Copyright Office

Dopo le parti 1 e 2,  è ora uscita la parte 3 dell’ampio studio dello US Copyright Office sul rapporto tra AI e diritto di autore (Copyright and Artificial Intelligence Part 3: Generative AI Training, May 2025).

La parte 3 (come anticipato nel mio post 28.02.2025  sulla parte 2) riguarda la questione del se lo sviluppo o in generale la preparazione  dell’AI su materiali protetti incida sui relativi diritti.

La risposta è positiva. Resta allora da capire -nel diritto USA- se sia invocabile la difesa del Fair Use: soluzione difficile, conclude l’Ufficio, per cui è auspicabile il diffondersi di un adeguato sistema di licenze.

La questione è più complicata nel diritto UE, dove manca una clausola generale permissiva di pari portata, essendovi invece eccezioni (o limitazioni) specificamente previste.

Ecco la Conclusione:

<<In applying current law, we conclude that several stages in the development of
generative AI involve using copyrighted works in ways that implicate the owners’ exclusive rights. The key question, as most commenters agreed, is whether those acts of prima facie infringement can be excused as fair use.
The fair use determination requires balancing multiple statutory factors in light of all relevant circumstances. Although it is not possible to prejudge the result in any particular case, precedent supports the following general observations:
Various uses of copyrighted works in AI training are likely to be transformative. The extent to which they are fair, however, will depend on what works were used, from what source, for what purpose, and with what controls on the outputs—all of which can affect the market. When a model is deployed for purposes such as analysis or research—the types of uses that are critical to international competitiveness—the outputs are unlikely to substitute for expressive works used in training. But making commercial use of vast troves of copyrighted works to produce expressive content that competes with them in existing markets, especially where this is accomplished through illegal access, goes beyond established fair use boundaries.
For those uses that may not qualify as fair, practical solutions are critical to support ongoing innovation. Licensing agreements for AI training, both individual and collective, are fast emerging in certain sectors, although their availability so far is inconsistent. Given the robust growth of voluntary licensing, as well as the lack of stakeholder support for any statutory change, the Office believes government intervention would be premature at this time.
Rather, licensing markets should continue to develop, extending early successes into more contexts as soon as possible. In those areas where remaining gaps are unlikely to be filled, alternative approaches such as extended collective licensing should be considered to address any market failure.
In our view, American leadership in the AI space would best be furthered by supporting both of these world-class industries that contribute so much to our economic and cultural advancement. Effective licensing options can ensure that innovation continues to advance without undermining intellectual property rights. These groundbreaking technologies should benefit both the innovators who design them and the creators whose content fuels them, as well as the general public.
Finally, as in prior Parts of this Report, the Office recognizes that facts on the ground are evolving at a rapid pace. We will continue to monitor developments in technology, case law, and markets, and to offer further assistance to Congress as it considers these issues >>

Il digital lending di e-books da parte di Internet Archive non costituisce “fair use”

Così l’appello del 2° circuito 4 settembre 2024,  Docket No. 23-1260, HACHETTE BOOK GROUP , INC., HARPERCOLLINS PUBLISHERS L.L.C., JOHN WILEY &
SONS , INC., PENGUIN RANDOM HOUSE LLC contro Internet Archive (MENASHI, ROBINSON, and KAHN Circuit Judges), su un tema ancora controverso pure in UE.

Internet Archive (poi: IA) scansiona in toto libri senza fine di lucro (<<is it “fair use” for a nonprofit organization to scan copyright-protected print books in their entirety anddistribute those digital copies online, in full, for free, subject to a one-to-one owned-to-loaned ratio between its print copies and the digital copies it makes available at any given time, all without authorization from the copyright-holding publishers or authors?>>, p. 7; dettagli sul fatto p. 11).

La ratio della tutela da copyright è prevalebntemente pubblicistica: promuovere la creazione di opere. V. : <<The monopoly created by the Copyright Act “rewards the individual author in order to benefit the public”; the idea being that authors and inventors will be more motivated to produce new works if they know those works will be protected, and the public will benefit from both restricted access to those works in the short term and unfettered access in the long term, once the period of exclusive control expires. Harper & Row, 471 U.S. at 546. The Act therefore “reflects a balance of competing claims upon the public interest: Creative work is to be encouraged and rewarded, but private motivation must ultimately serve the cause of promoting broad public availability of literature, music, and the other arts.” Twentieth Century Music Corp. v. Aiken, 422 U.S. 151, 156 (1975)>> p. 18

Dei quattro fattori da conteggiare secondo il § 107, nessuno è a favore di IA,.  Circa il primo, è vero che la commerciality lo è; ma ciò è controbilanciato dalla Transformativeness, che, da un lato, è a favore degli editori e, dall’altro, è più importante, p. 21 e 38/9.

Ne dà notizia Ars Technica che offre pure il link diretto al documento .

Sentenza interessante, anche se la disciplina del fair use è un pò diversa da quella nazionale/europea.

Da noi v. gli ottimi lavori si Caterina Sganga sull’esaurimento digitale nel copyright UE (ad es. in Diritto dell’informazione e dell’informatica 2020-3  e 2019-1).

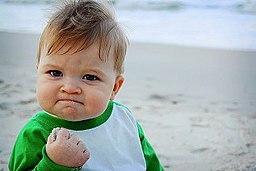
Fair use (negato) sull’uso non autorizzato in campagna elettorale di fotografia di bambino

Lo US 8th circuit of appeal con sentenza 7 giugno 2024, No. 22-3623 e No. 23-2117 , Griner c. King +1 , sull’uso indebito in campagna elettorale della famosa fotografia cd Success kid, qui sotto riprodotta:

Il centro della sentenza è la ricorrenza o meno di fair use (essendo stato azionato il diritto di autore sulla fotografia registrata dal papà al Copyright Office): fair fair use che non viene ravvisato.

(dal blog di Eric Goldman)

Copyright e standards

La corte di appello del distretto di Columbia , 12.09.2023, No. 22-7063, AMERICAN SOCIETY FOR TESTING AND MATERIALS, ET AL v. PUBLIC.RESOURCE.ORG, INC., dà qualche interessante insegnamento sul tema (qui la pagina della corte mentre  qui il link diretto al pdf).

Tre organizzazioni, che predispongno standard per certi settori di impresa, fanno causa a public.resource.org, per aver pubblicato centinaia di standards: il che violerebbe il copyright su di essi gravante.

Di questi la maggior parte era anche stata inserita (incorporate) nella legislazione usa.

La corte di appello dice che tale pubblicaizone da parte di https://public.resource.org/ costituisce fair use (per la parte incorporated).

I primi tre fattori del 17 us code § 107 sono a favore del convenuto.

L’ultimo (effetti economici sul mercato dell’opera protetta) è invece incerto: ma non basta a controbilanciare gli altri tre.

<<n ASTM II, we noted that Public Resource’s copying may harm the market for the plaintiffs’ standards, but we found the extent of any such harm to be unclear. 896 F.3d at 453. We noted three considerations that might reduce the amount of harm: First, the plaintiffs themselves make the incorporated standards available for free in their reading rooms. Second, Public Resource may not copy unincorporated standards—or unincorporated portions of standards only partially incorporated. Third, the plaintiffs have developed and copyrighted updated versions of the relevant standards, and these updated versions have not yet been incorporated into law. We asked the parties to address these issues, among others, on remand. See id.
The updated record remains equivocal. The plaintiffs press heavily on what seems to be a common-sense inference: If users can download an identical copy of an incorporated standard for free, few will pay to buy the standard. Despite its intuitive appeal, this argument overlooks the fact that the plaintiffs regularly update their standards—including all 185 standards at issue in this appeal. And regulators apparently are much less nimble in updating the incorporations. So, many of the builders, engineers, and other regular consumers of the plaintiffs’ standards may simply purchase up-to-date versions as a matter of course. Moreover, some evidence casts doubt on the plaintiffs’ claims of significant market injury. Public Resource has been posting incorporated standards for fifteen years. Yet the plaintiffs have been unable to produce any economic analysis showing that Public Resource’s activity has harmed any relevant market for their standards. To the contrary, ASTM’s sales have increased over that time; NFPA’s sales have decreased in recent years but are cyclical with publications; and ASHRAE has not pointed to any evidence of its harm. See ASTM III, 597 F. Supp. 3d at 240.
The plaintiffs’ primary evidence of harm is an expert report opining that Public Resource’s activities could put the plaintiffs’ revenues at risk. Yet although the report qualitatively describes harms the plaintiffs could suffer, it makes no serious attempt to quantify past or future harms. Like the district court, we find it “telling” that the plaintiffs “do not provide any quantifiable evidence, and instead rely on conclusory assertions and speculation long after [Public Resource] first began posting the standards.” ASTM III, 597 F. Supp. 3d at 240.
Finally, our analysis of market effects must balance any monetary losses to the copyright holders against any “public benefits” of the copying. Oracle, 141 S. Ct. at 1206. Thus, even if Public Resource’s postings were likely to lower demand for the plaintiffs’ standards, we would also have to consider the substantial public benefits of free and easy access to the law. As the Supreme Court recently confirmed: “Every citizen is presumed to know the law, and it needs no argument to show that all should have free access” to it. Georgia v. Public.Resource.Org., Inc., 140 S. Ct. 1498, 1507 (2020) (cleaned up)>>.

Sintesi sul quarto:

<<We conclude that the fourth fair-use factor does not significantly tip the balance one way or the other. Common sense suggests that free online access to many of the plaintiffs’ standards would tamp down the demand for their works. But there are reasons to doubt this claim, the record evidence does not strongly support it, and the countervailing public benefits are substantial.>>

Sintesi comlpèessiva: <<In sum, the first three factors under section 107 strongly favor fair use, and the fourth is equivocal. We thus conclude that Public Resource’s non-commercial posting of incorporated standards is fair use>>

La citazione in giudizio dell’associazione scrittori usa contro Open AI

E’ reperibile in rete (ad es qui) la citazione in giuidizio avanti il South. Dist. di New Yoerk contro Open AI per vioalzione di copyright proposta dalla importante Autorhs Guild e altri (tra cui scrittori notissimi) .

L’allenamento della sua AI infatti pare determini riproduzione e quindi (in assenza di eccezione/controdiritto) violazione.

Nel diritto UE l’art. 4 della dir 790/2019 presuppone il diritto  di accesso all’opera per  invocare l’eccezione commerciale di text and data mining:

<< 1. Gli Stati membri dispongono un’eccezione o una limitazione ai diritti di cui all’articolo 5, lettera a), e all’articolo 7, paragrafo 1, della direttiva 96/9/CE, all’articolo 2 della direttiva 2001/29/CE, all’articolo 4, paragrafo 1, lettere a) e b), della direttiva 2009/24/CE e all’articolo 15, paragrafo 1, della presente direttiva per le riproduzioni e le estrazioni effettuate da opere o altri materiali cui si abbia legalmente accesso ai fini dell’estrazione di testo e di dati.

2. Le riproduzioni e le estrazioni effettuate a norma del paragrafo 1 possono essere conservate per il tempo necessario ai fini dell’estrazione di testo e di dati.

3. L’eccezione o la limitazione di cui al paragrafo 1 si applica a condizione che l’utilizzo delle opere e di altri materiali di cui a tale paragrafo non sia stato espressamente riservato dai titolari dei diritti in modo appropriato, ad esempio attraverso strumenti che consentano lettura automatizzata in caso di contenuti resi pubblicamente disponibili online.

4. Il presente articolo non pregiudica l’applicazione dell’articolo 3 della presente direttiva>>.

Il passaggio centrale (sul se ricorra vioalzione nel diritto usa) nella predetta citazione sta nei §§ 51-64:

<<51. The terms “artificial intelligence” or “AI” refer generally to computer systems designed to imitate human cognitive functions.
52. The terms “generative artificial intelligence” or “generative AI” refer specifically to systems that are capable of generating “new” content in response to user inputs called “prompts.”
53. For example, the user of a generative AI system capable of generating images
from text prompts might input the prompt, “A lawyer working at her desk.” The system would then attempt to construct the prompted image. Similarly, the user of a generative AI system capable of generating text from text prompts might input the prompt, “Tell me a story about a lawyer working at her desk.” The system would then attempt to generate the prompted text.
54. Recent generative AI systems designed to recognize input text and generate
output text are built on “large language models” or “LLMs.”
55. LLMs use predictive algorithms that are designed to detect statistical patterns in the text datasets on which they are “trained” and, on the basis of these patterns, generate responses to user prompts. “Training” an LLM refers to the process by which the parameters that define an LLM’s behavior are adjusted through the LLM’s ingestion and analysis of large
“training” datasets.
56. Once “trained,” the LLM analyzes the relationships among words in an input
prompt and generates a response that is an approximation of similar relationships among words in the LLM’s “training” data. In this way, LLMs can be capable of generating sentences, p aragraphs, and even complete texts, from cover letters to novels.
57. “Training” an LLM requires supplying the LLM with large amounts of text for
the LLM to ingest—the more text, the better. That is, in part, the large in large language model.
58. As the U.S. Patent and Trademark Office has observed, LLM “training” “almost
by definition involve[s] the reproduction of entire works or substantial portions thereof.”4
59. “Training” in this context is therefore a technical-sounding euphemism for
“copying and ingesting.”
60. The quality of the LLM (that is, its capacity to generate human-seeming responses
to prompts) is dependent on the quality of the datasets used to “train” the LLM.
61. Professionally authored, edited, and published books—such as those authored by Plaintiffs here—are an especially important source of LLM “training” data.
62. As one group of AI researchers (not affiliated with Defendants) has observed,
“[b]ooks are a rich source of both fine-grained information, how a character, an object or a scene looks like, as well as high-level semantics, what someone is thinking, feeling and how these states evolve through a story.”5
63. In other words, books are the high-quality materials Defendants want, need, and have therefore outright pilfered to develop generative AI products that produce high-quality results: text that appears to have been written by a human writer.
64. This use is highly commercial>>

Plagio di lettera da parte di un breve saggio: “The Kindest” in Larson v. Dorland Perry

La corte del Massachussets 14.09.2023 n. Case 1:19-cv-10203-IT, larson v. Dorland Perry, (segnalato e linkato dal prof. Edward Lee su X ).

Qui la peculiarità fattuale è che il lavoro plagiario si è evoluto in tre versioni, sempre più lontane dal lavoro originale.

Sulla substantial similarity : <<“Substantial similarity is an elusive concept, not subject to precise definition.” Concrete Mach. Co. v. Classic Lawn Ornaments, Inc., 843 F.2d 600, 606 (1st Cir. 1988). The inquiry is a “sliding scale”: If there are many ways to express a particular idea, then the burden of proof on  the plaintiff to show substantial similarity is lighter. Id. at 606-07. Here, there are many ways to write a letter, even one dealing specifically with kidney donations. Larson Mem. SJ, Ex. 8 [Doc. No. 189-8] (examples of sample letters from organ donors/family members of organ donors to recipients); Id., Ex. 1 ¶ 7 (Larson Aff.) [Doc. No. 189-1]>>.

Sulle parti non originali:

<<However, “[n]o infringement claim lies if the similarity between two works rests necessarily on non-copyrightable aspects of the original—for example, ‘the underlying ideas, or expressions that are not original with the plaintiff.’” TMTV, Corp. v. Mass. Prods., Inc., 645 F.3d 464, 470 (1st Cir. 2011) (internal citation omitted). “[I]t is only when ‘the points of dissimilarity not only exceed the points of similarity, but indicate that the remaining points of similarity are (within the context of plaintiff’s work) of minimal importance either quantitatively or qualitatively, [that] no infringement results.’” Segrets, Inc., 207 F.3d at 66. “‘The test is whether the accused work is so similar to the plaintiff’s work that an ordinary reasonable person would conclude that the defendant unlawfully appropriated the plaintiff’s protectible expression by taking material of substance and value.’” Id. at 62. “While summary judgment for a plaintiff on these issues is unusual,” it may be warranted based on the factual record. Id.; accord T-Peg, Inc. v. Vt. Timber Works, Inc., 459 F.3d 97, 112 (1st Cir. 2006)>>.

Sui dati fattuali sostenenti il giudizio di accertato plagio nella prima versione:

<<The 2016 Brilliance Audio Letter.8 As Larson concedes, the undisputed evidence mandates a conclusion that the 2016 Letter is substantially similar to the Dorland Letter. The Dorland Letter is approximately 381 words long, Dorland Mem. SJ, Ex. C [Doc. No. 181-3]; of those 381 words, the 2016 Letter copies verbatim approximately 100, and closely paraphrases approximately 50 more, Larson Mem. SJ, Appendix I [Doc. No. 193-1]. Many of these verbatim or near-verbatim lines gave the Dorland Letter its particular character, including: “My gift…trails no strings”; “I [focused/channeled] [a majority of] my [mental] energ[y/ies] into imagining and celebrating you”; “I accept any level of involvement,…even if it is none”; “To me the suffering of strangers is just as real”; and “I [wasn’t given/didn’t have] the opportunity to form secure attachments with my family of origin.” Id. The 2016 Letter also follows an identical structure to the Dorland Letter: a paragraph introducing the donor, including information on race, age, and gender; a paragraph explaining how the donor discovered the need for kidney donation; a paragraph explaining the donor’s traumatic childhood; a paragraph expressing the donor’s focus on the future recipient; a paragraph wishing the recipient health and happiness; and a concluding paragraph expressing a desire to meet. Id. Based on the documents before the court, the 2016 Letter took “material of substance and value” from the Dorland Letter in such a quantity and in such a manner that the points of similarity outweigh the points of dissimilarity. See Segrets, Inc., 207 F.3d at 62, 66.>>

Con analitico esame ravvisa comunque fair use.

Il giudice esclude tortiuous interference nelle continue dichiaraizoni dell’asserito plagiato verso le contriopati contrattiuali dell’asserito plagiante

Esclude anche che ricorra diffamazione.

Fair use nel software: la sentenza di appello in Apple v. Corellium

L’appello dell’11 circuito 8 maggio 2023, Apple v. Corellium, Case: 21-12835, decide un interessante caso di fair use nel software.

Si tratta del sftw CORSEC per simulare il sistema operativo iOS di Apple anche su macchine android.

La corte di appello conferma il fair use, dati i benefici per la collettività di tale sftw.

<< Like Google Books, CORSEC adds new features to copyrighted works. CORSEC allows re-searchers to visualize in real time iOS’s processes, freeze those pro-cesses and study them for as long as they need to, step backward and forward in time at will to closely monitor system activity, and run multiple experiments from the same starting point. CORSEC also adds file and app browsers. There’s no dispute that these fea-tures assist researchers and enable them to do their work in new ways. Corellium has thus “augment[ed] public knowledge by mak-ing available information about [iOS].” Id. at 207; see also A.V. ex rel. Vanderhye v. iParadigms, LLC, 562 F.3d 630, 639 (4th Cir. 2009) (finding that copying student assignments into a database to detect plagiarism was “transformative” because the database’s “use of [the students’] works had an entirely different function and pur-pose than the original works”); Perfect 10, Inc. v. Amazon.com, Inc., 508 F.3d 1146, 1165 (9th Cir. 2007) (finding that Google image search’s “use of thumbnails [was] highly transformative” because the “use of the images served a different function” than the original pictures by “improving access to information on the internet ver-sus artistic expression” (cleaned up)); Sony Comput. Ent., Inc. v. Connectix Corp., 203 F.3d 596, 606 (9th Cir. 2000) (finding that a PlayStation emulator was “modestly transformative” because the emulator “create[d] a new platform, the personal computer, on which consumers can play games designed for the Sony PlayStation”) >>.

Apple solleva tre obieizoni, rigettate dalla Corte.

<<Against all this, Apple advances three arguments—all unpersuasive.

First, Apple argues that “making verbatim copies of a cop-yrighted work and converting [those works] into a different format is not transformative.” Apple is right. In Patton, for example, we found no transformative use where “verbatim copies of portions of . . . original books . . . ha[d] merely been converted into a digital format.” 769 F.3d at 1262. Similarly, the Ninth Circuit held that it was not transformative to convert copyrighted songs from CDs to MP3 files for download because the “original work[s] [were] merely retransmitted in a different medium.” See A&M Recs., Inc. v. Napster, Inc., 239 F.3d 1004, 1015 (9th Cir. 2001).
But this isn’t a case in which the original is simply repack-aged in a different format. Corellium adds several features that are not normally available on iOS. These include (1) the ability to see and halt running processes; (2) the ability to modify the kernel; (3) CoreTrace, a tool to view system calls; (4) an app browser; (5) a file browser; and (6) the ability to take live snapshots. They also include, for example, the ability to modify the trust cache so that researchers can install new programs on the device that allow the user to perform fuzzing (a way to find bugs in a product’s code) or other types of security research. The record, in other words, shows that there wasn’t verbatim copying here. And even if there were, Patton itself recognized that “verbatim copying may be transform-ative so long as the copy serves a different function than the origi-nal work.” 769 F.3d at 1262. Here, Corellium used iOS to serve a research function, and not as a consumer electronic device.
Second, Apple contends that “[s]ecurity research is not a transformative purpose because it is one of the purposes already served by Apple’s works.” Apple says that “security researchers have long used Apple-licensed versions of iOS to do their work.” Corellium (in our view) rightly points out the flaw in this argu-ment: it’s “like saying Google Books was not transformative be-cause scholars could manually search books for keywords by going to the library.” In other words, there’s no dispute that CORSEC “adds features that are not available on retail iOS that are useful for security research.” These features make security research far more efficient. See Fox News Network, LLC v. TVEyes, Inc., 883 F.3d 169, 177 (2d Cir. 2018) (noting “the transformative purpose of en-hancing efficiency”). They also make possible deeper insights into the software. The fact that iOS itself allowed for some security re-search before, then, can’t negate Corellium’s innovation (just like sifting through books at the library didn’t negate Google Books’s transformativeness).
Third, Apple asserts that “the district court was wrong to find—on summary judgment—that the purpose of [CORSEC] is security research.” For this, Apple mostly points to evidence show-ing that customers can use CORSEC for multiple purposes. For example, Corellium’s expert testified that security research wasn’t CORSEC’s “exclusive use.” But transformativeness does not re-quire unanimity of purpose—or that the new work be entirely dis-tinct—because works rarely have one purpose. In assessing whether a work is transformative, the question has always been “whether a [transformative use] may reasonably be perceived.” Campbell, 510 U.S. at 582 (emphasis added) (finding that a parody was transformative even though both a song and its parody serve the same function of entertainment). We don’t ask whether the new product’s only purpose is transformative.
The Supreme Court made this point in Google. In that case, Google used Java’s code “for the same reason that [Oracle] created those portions, namely, to enable programmers [to use shortcuts] that would accomplish particular tasks.” Google, 141 S. Ct. at 1203. But, at a higher level, the purpose was to create a “new product [that] offer[ed] programmers a highly creative and innovative tool for a smartphone environment.” Id. This higher-order purpose was what made Google’s product transformative. Id. As in Google, the mere fact that some purposes overlap does not pre-clude a finding of transformative use >>

Editori contro Internet Archive: sentenza della corte newyorkese sul fair use relativo alla digitalizzazione di libri cartacei

Distretto Sud di New York 24 marzo 2023, 20-cv-4160 (JGK), Hachette ed altri c. Internet Archive ed altri.

Interne Archive , non profit, durante la pandemia digitalizzò 127 libri cartacei di 4 editori e li mise on line. Questi agiscono in giudizio per violaizone di diritto di autore.

La difesa di IA consistette solo nell’eccezione di  fair use (17 us code § 107).

Eccezione rigettata però.

Tra i punti più interessanti:

i) la differenza rispetto al caso Google Books (che pure digitalizza libri cartacei), ove fu ravvisato transformative use, sub A.1, pp. 19-20.

ii) l’aver ravvisato profit indiretto, anche se l’associazione è non profit, sub A.2 p. 26 ss